HaWMPO Down-Weights Hallucinated World-Model Rollouts
World-model RL is cheap until the dream lies. HaWMPO, from Jilin University and JD’s Joy Future Academy, is a September 9 paper that tries to catch those lies before they update the policy.
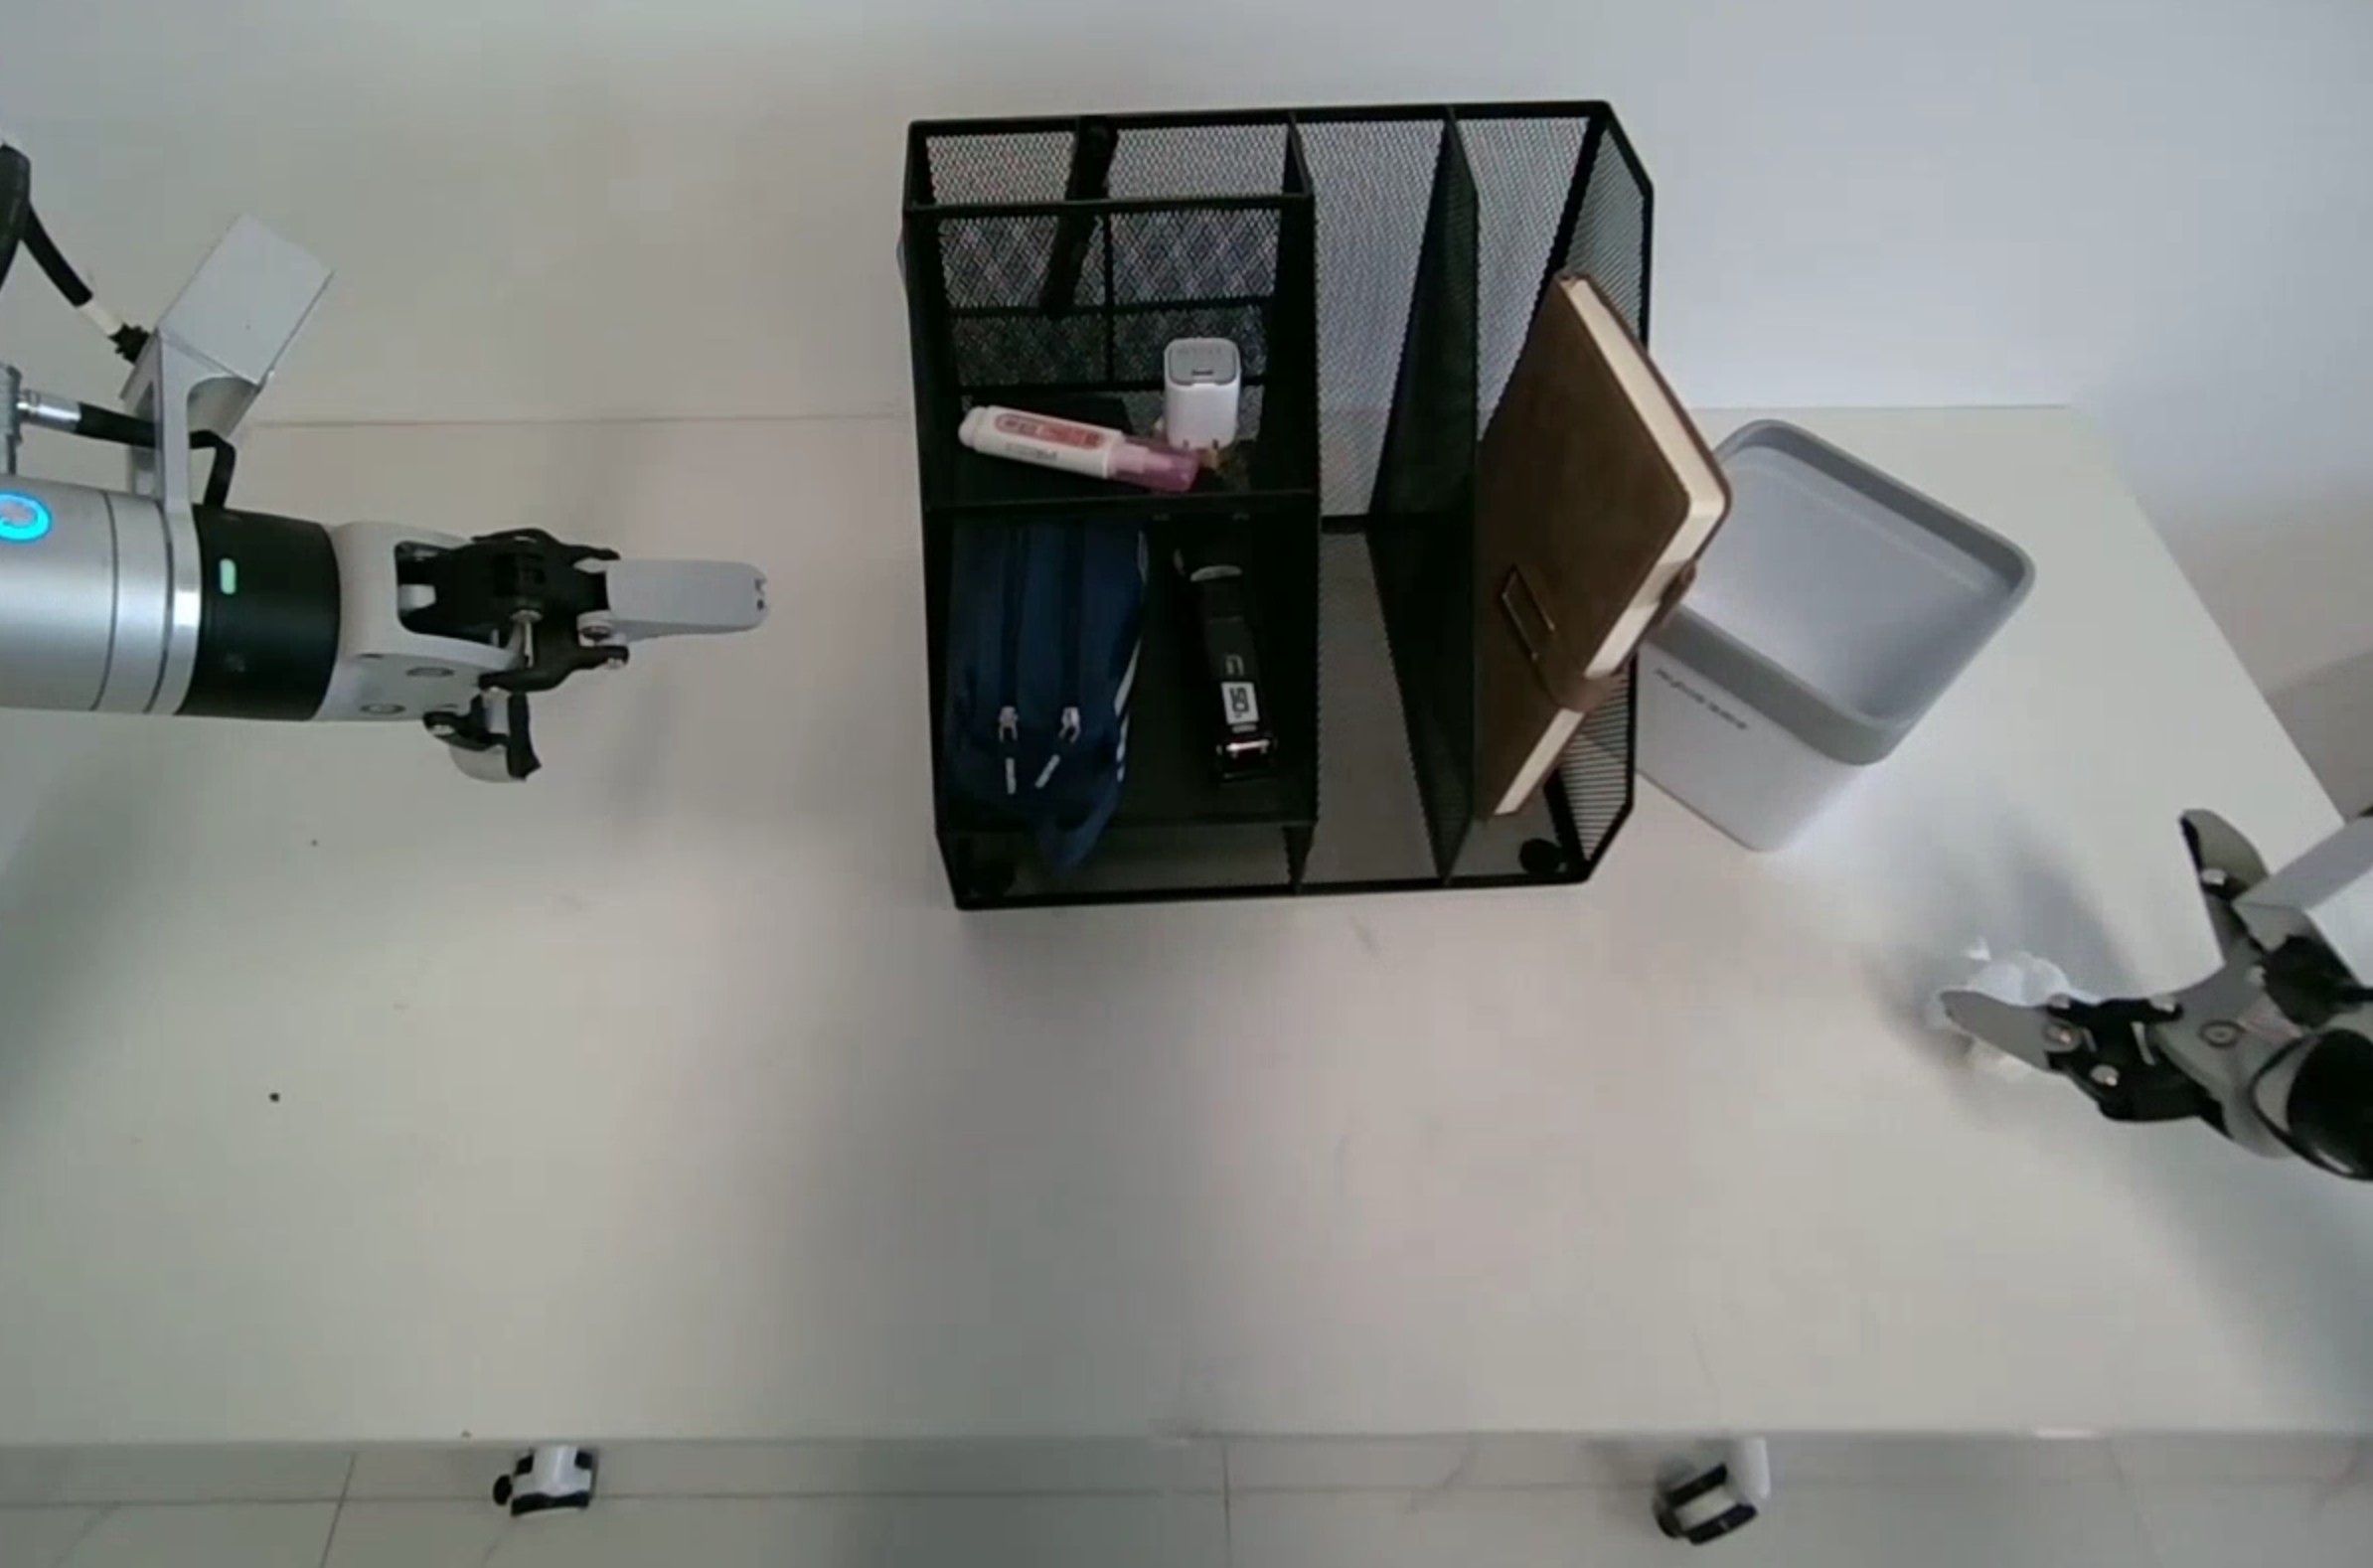
The method post-trains a VLA inside an action-conditioned world model, then runs a hallucination-aware model (HAM) over each generated 8-frame chunk. A Reward-Soft term scales the chunk reward by (1 − α · H). High-H chunks still exist. They just count less.
On LIBERO Spatial / Goal / Object, HaWMPO’s average success is 63.7%, 15.0 points over one-shot SFT OpenVLA-OFT (48.7%) and 2.8 over the authors’ reproduced WoVR* (60.9%). Spatial is the big lift: 77.2% versus 69.2%.
Score the dream, then GRPO
The world model is an action-conditioned Wan2.2-TI2V-5B. It sees five RGB frames (one fixed reference plus four recents) and an 8-step action chunk, then predicts eight future frames at 256×256. The VLA rolls the next chunk on those frames. Eight parallel imagined environments feed GRPO. Training ran on 8 NVIDIA H200s.
HAM fuses the predicted chunk, the actions, the current frame, and the rollout’s first frame through a frozen DINOv3 encoder and a four-layer fusion transformer. Supervision is a composite of DINOv3 similarity, depth consistency, optical-flow trajectory consistency, and MUSIQ. Against 50 human-labeled LIBERO chunks (18 hallucinated, 32 not), HAM’s AUROC is 0.9375. MUSIQ alone is useless.
The authors are honest about the proxy: task failure is not hallucination, and the four metrics are not physics.
Two G1 chores
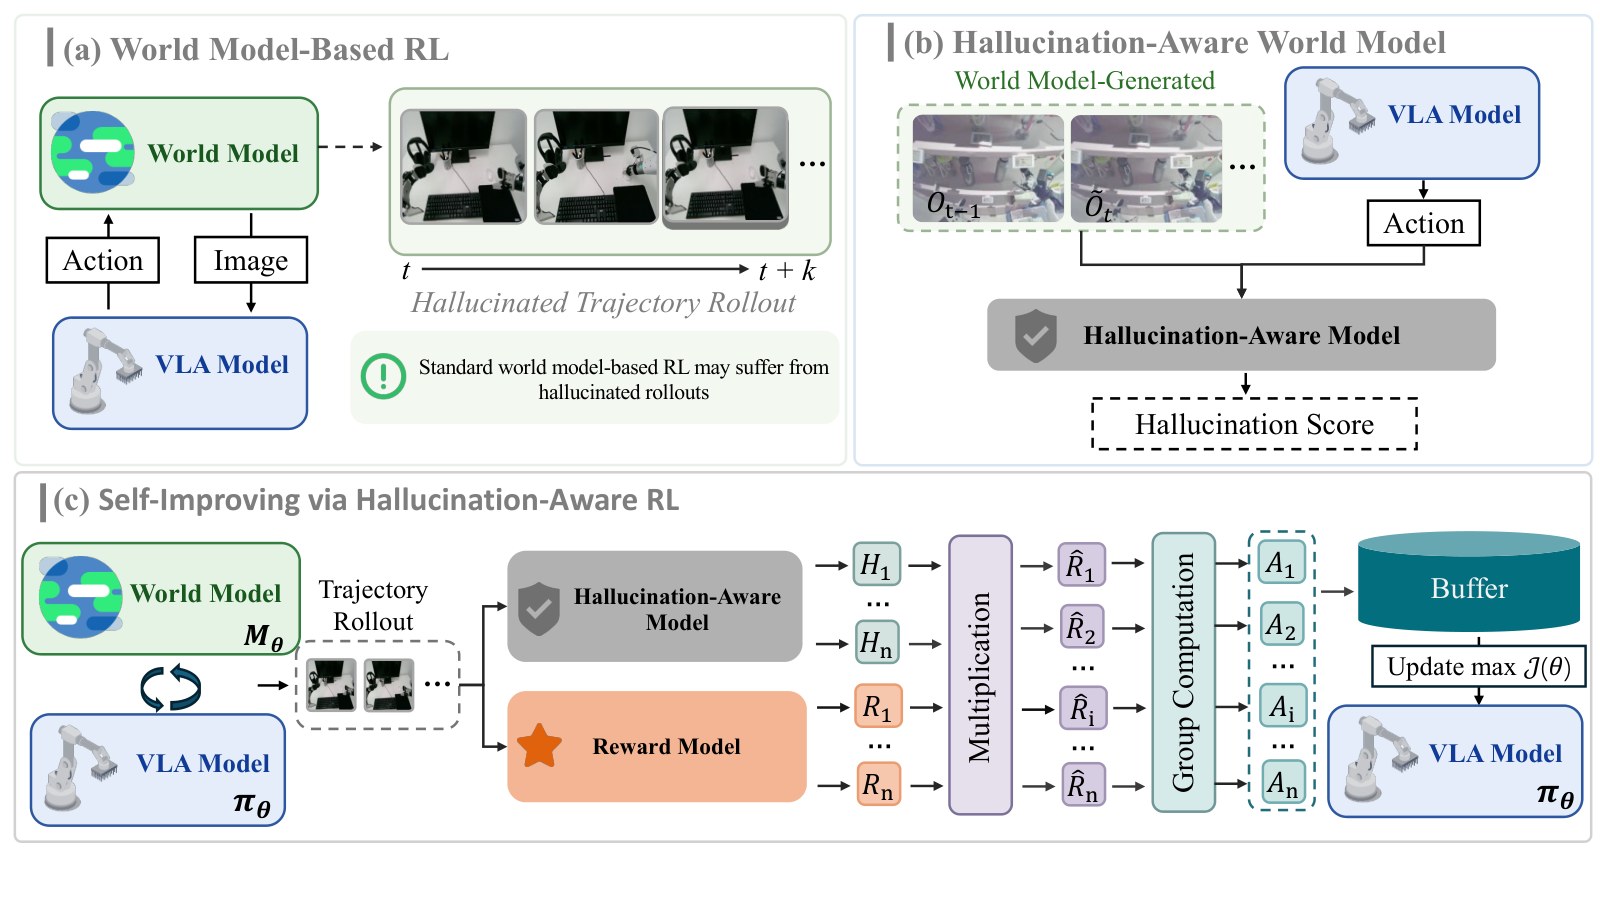
Hardware is a G1. Two tasks, 20 trials each, pedal off at eval:
| Method | Tissue-to-Box | Headphone-on-Stand | Average |
|---|---|---|---|
| SFT OpenVLA-OFT | 75% (15/20) | 60% (12/20) | 67.5% |
| WoVR | 80% (16/20) | 65% (13/20) | 72.5% |
| HaWMPO | 85% (17/20) | 75% (15/20) | 80.0% |
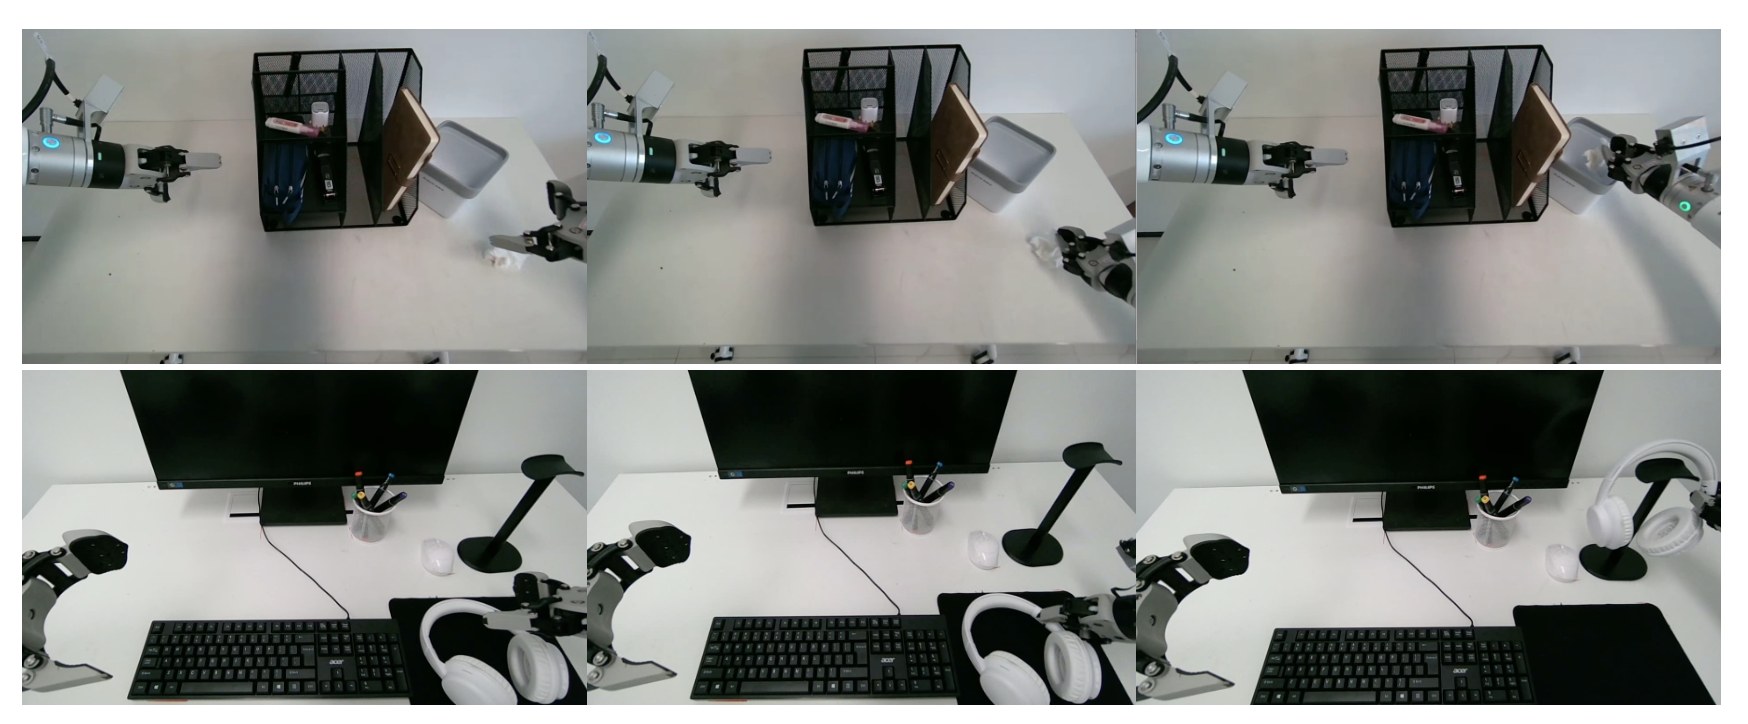
That is a 12.5-point bump over the base policy. The paper calls it preliminary. It is two tasks.
Penalty strength α is task-dependent. Object and Spatial like 0.3. Goal likes 1.0. Strip HAM (and Reward-Soft with it) and Spatial drops 8.0–11.6 points depending on step count.
A Human’s Take
I like that they treated world-model RL as a lying intern, not an oracle. Down-weighting the pretty-but-wrong rollouts is the grown-up move. 80% on tissue-in-box is still a lab chore, and Goal did not love the same α as Spatial. If you cannot trust the dream equally across task families, you do not have a generalist trainer. You have a knob.